本课程带你用Python、DuckDB与dbt从零搭建端到端ELT分析工程:借Faker生成电商数据,按勋章架构完成Bronze到Gold的SQL转换与自动化质量测试,并用Streamlit打造交互式仪表盘,Git与GitHub托管,是打造数据工程作品集的实战教程。
原始标题:Analytics Engineering: Build an End-to-End ELT Data Pipeline
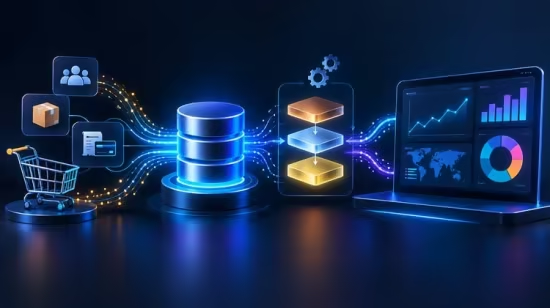
这个ELT项目是一个基于现代数据栈(Modern Data Stack)的本地化端到端分析工程实战。它通过 Python 的 Faker 库自建真实的电商数据集,并以高性能的 DuckDB 作为本地数据仓库,完美绕过了云端数仓的昂贵成本。项目核心采用标准的勋章架构(Medallion Architecture),利用 dbt 完成从原始数据(Bronze)到数据清洗(Silver),再到高价值业务指标(Gold)的逐层 SQL 转换,并在其间嵌入了自动化数据质量测试(如唯一性与非空校验),从而搭建起一条工业级的自动化数据管线。
在产出端与工程实践上,该项目紧密结合了数据可视化与专业研发工作流。通过 Python 驱动连接 DuckDB,利用 Streamlit 和 Plotly 快速构建出直观的交互式执行官分析仪表盘,动态呈现总营收、毛利润率及商品品类表现等核心 KPI。整个项目完全通过 Git 进行版本控制,并最终托管于 GitHub,配合规范的目录结构(Models、Tests、Scripts)与详尽的 README 架构文档,不仅构成了一个完整的闭环分析工程体系,更是大数据工程师和分析工程师展现个人硬实力的高质量职场作品集(Portfolio)。
Published 9/2026
MP4 | Video: h264, 1920×1080 | Audio: AAC, 44.1 KHz, 2 Ch
Language: English | Duration: 3h 34m | Size: 1.43 GB
Build a real-world ELT project with Python, SQL, DuckDB, dbt, automated testing, Streamlit dashboards and GitHub
What you’ll learn
Build an end-to-end Analytics Engineering ELT pipeline from scratch.
Generate realistic synthetic e-commerce datasets using Python, pandas, and Faker.
Use DuckDB as a high-performance local analytical data warehouse.
Load CSV datasets into DuckDB using dbt seeds.
Build and organise dbt models using Bronze, Silver, and Gold data architecture.
Create reusable staging models to clean, cast, rename, and standardise raw data.
Build business-ready fact tables by joining and transforming multiple datasets with SQL and dbt.
Calculate business metrics including gross revenue, total cost, gross profit, and profit margin.
Implement automated dbt data-quality tests for unique, not-null, and accepted values.
Run and validate dbt transformations and troubleshoot data-model issues.
Query transformed DuckDB data with Python to verify business KPIs and analytical results.
Build an interactive executive analytics dashboard using Streamlit and Plotly.
Visualise revenue, profit trends, order performance, and product category performance.
Structure an Analytics Engineering project using professional folders, models, tests, scripts, and documentation.
Create a professional GitHub README documenting the project architecture, technology stack, data flow, and results.
Use Git to initialise a repository, stage files, create commits, and manage project source code.
Publish a completed Analytics Engineering portfolio project to a remote GitHub repository.
Description
Build a complete, hands-onAnalytics Engineering project from start to finish using Python, SQL, DuckDB, dbt, Streamlit, Plotly, Git, and GitHub.
This course is designed for learners who want to understand how modern analytics pipelines work by actually building one. Rather than focusing only on theory, you will create a practicale-commerce ELT pipeline that takes data from its raw form through transformation and testing to business-ready analytics and an interactive executive dashboard.
You will begin by usingPython, pandas, and Faker to generate realistic synthetic datasets containing customers, products, and orders. You will then useDuckDB as a fast, lightweight analytical data warehouse for the project.
Next, you will work withdbt — data build tool — to transform your data using a structuredBronze, Silver, and Gold architecture. You will create staging models to clean and standardise the data before building a business-ready fact table containing important calculations such as gross revenue, total cost, and gross profit.
Data quality is an essential part of Analytics Engineering, so you will also implementautomated dbt tests to validate important rules including unique values, not-null values, and accepted values.
Once the transformation pipeline is complete, you will query the analytical warehouse using Python and calculate executive KPIs includingcompleted orders, gross revenue, gross profit, and profit margin.
You will then turn your analytical data into business insights by building aninteractive Streamlit dashboard with Plotly. The dashboard will include KPI cards, monthly revenue and profit trends, product category performance, and interactive data visualisations.
But the project does not end with the dashboard.
You will learn how to organise and document your project professionally. You will create a detailedREADME, document the project architecture and technology stack, configure a .gitignore file, and prepare the project for source control.
Finally, you will useGit and GitHub to initialise your repository, stage and commit your source code, connect to a remote repository, and publish the completed project online.
By the end of the course, you will understand howPython, SQL, DuckDB, dbt, Streamlit, and GitHub work together as part of a modern Analytics Engineering workflow.
Most importantly, you will finish with a complete, documentedportfolio-ready Analytics Engineering project that demonstrates practical end-to-end skills you can continue developing and showcase on GitHub.
Who this course is for
Beginners interested in Analytics Engineering or Data Engineering who want to learn by building a complete hands-on project.
Aspiring Analytics Engineers and Data Engineers looking to develop practical, portfolio-ready skills.
Data Analysts who want to move beyond analysis and learn how data is generated, stored, transformed, tested, and prepared for reporting.
Python and SQL learners who want to apply their skills to a realistic end-to-end data project.
dbt beginners who want practical experience building staging models, business marts, and automated data-quality tests.
Developers and technology professionals interested in learning modern ELT workflows using Python, DuckDB, dbt, Streamlit, and Plotly
Students and career changers looking for a structured project that demonstrates modern Analytics Engineering concepts and tools.
Anyone building a technical portfolio who wants to create, document, and publish an end-to-end Analytics Engineering project on GitHub.
此处内容需要权限查看
会员免费查看